Second-party data sharing: a guide for B2B GTM teams


Your partners know things about your target accounts that you don’t. Which ones already run an adjacent product. Which ones just expanded their contract. Which ones are actively engaging with their team right now.
That knowledge has a name: second-party data. Second-party data is one organization’s first-party data, shared directly with another organization under a partnership agreement and for a defined purpose.
The key word is “direct.” The company that collected the data knows its origin and consent terms, and the partner receiving it can ask for proof. Third-party data is different: brokers aggregate and resell it, with little visibility into how it was gathered.
For B2B revenue teams, second-party data delivers account context, and that’s exactly what your reps and AI agents are missing.
The catch is governance. Consent scope, permitted uses, and measurement need to be settled before any data moves.
So let’s talk about how to do it right. This article defines second-party data, compares it with other data types, and walks through the checks and workflow that make partner data exchange safe and useful.
What is second-party data sharing?
The Interactive Advertising Bureau (IAB) put it this way in its "Understanding the Language of Data" article:
"Second-party data is someone else's first-party data. Typically, a company makes its first-party data available to another company for a defined purpose in a contractual agreement. This can take place in the form of a co-op."
CDP.com's glossary entry (updated September 17, 2026) describes it as another organization's first-party data "shared directly with your brand through a trusted partnership agreement." Its examples include shared CRM lists, co-op audience pools, retailer media data, and data clean room outputs.
Three elements recur in every credible definition:
- The data was collected by the sharing party through its own relationship with customers, prospects, or users.
- The exchange is direct and governed by a contract, not mediated by an anonymous broker.
- The agreement names a purpose, so use is limited to what both sides approved.
How does second-party data compare with first-party and third-party data?
The three categories differ on one question: who has the relationship with the person or account behind the data, and how visible is the chain from collection to your hands?
Data type versus cookie label
Third-party data and third-party cookies are separate things. "Third-party" in the data classification describes the relationship between the data holder and the end user.
A third-party cookie is a browser technology set by a domain other than the one the visitor is on. Cookie deprecation affects one way of collecting and targeting. It doesn't change what second-party data is, which is why partner exchange has drawn attention as an alternative source of signal.
Why does second-party data matter for GTM teams?
Go-to-market teams need audience and account context they can trust, and the broad, broker-sourced signals many teams relied on have become harder to depend on. Second-party data fills part of that gap with information that has a named origin and a documented consent chain.
Common examples include:
- Shared customer and prospect lists between technology partners, limited to accounts both parties agree to compare
- Shared audience pools built for joint campaigns
- Retailer or marketplace data shared with suppliers for planning and media
- Aggregated outputs from a clean room that show overlap or conversion without exposing records
Three reasons explain the value:
- Identity matching improves because both parties hold records tied to real relationships.
- Relevance is higher because the partner's customers already use products adjacent to yours.
- Incrementality is measurable, since you can compare outcomes for partner-informed outreach against a control group.
None of this makes second-party data a compliance shortcut. It reduces uncertainty about origin. It doesn't replace the need to verify it.
How does Crossbeam enable secure second-party data sharing?
Crossbeam treats partner data exchange as an operating system rather than a series of one-off data favors. Partners connect through the Crossbeam Network, which more than 30,000 companies use, and each side chooses what to share from its CRM. The platform then surfaces account overlap: which of your customers, prospects, and open opportunities also appear in a partner's data.
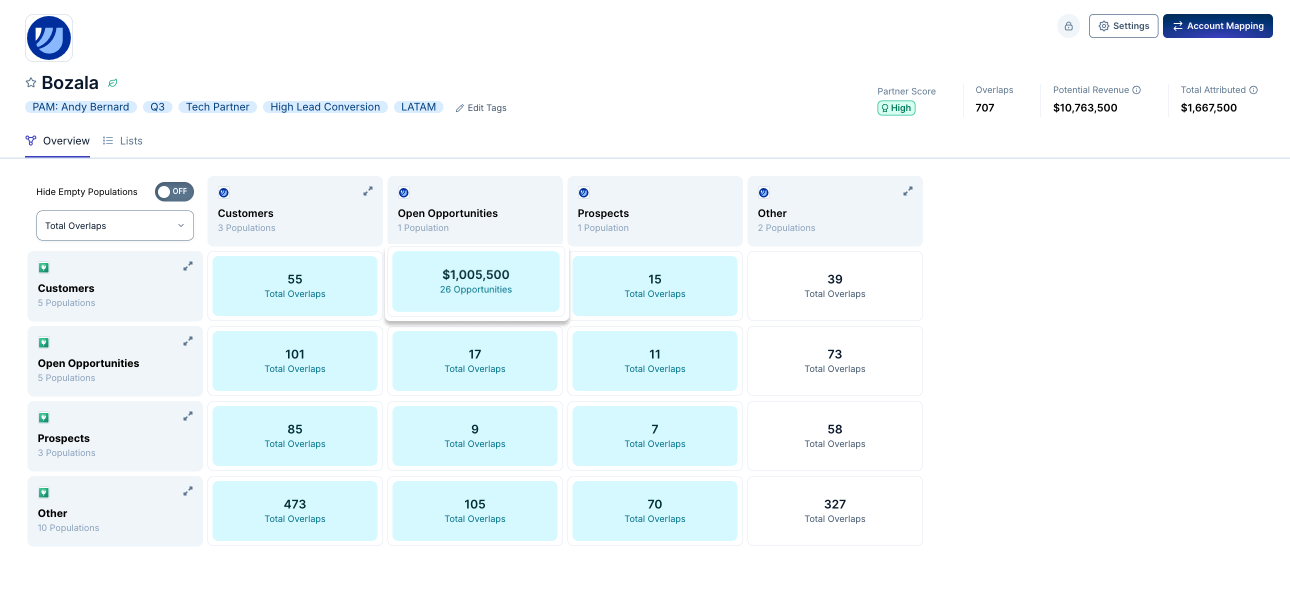
That overlap is the useful output. A rep sees that a target account is a customer of a partner, which suggests a warm introduction and a shared-customer story. A partnerships lead sees which partners overlap most with the pipeline. Neither needs a raw list emailed as a spreadsheet.
Distribution matters as much as discovery. Signals flow into the CRM and sales tools teams already use, including Salesforce, HubSpot, Gong, and Outreach. For RevOps teams, that means partner context supports segmentation, automation, and attribution inside existing systems. For AI workflows, the Crossbeam MCP server brings ecosystem data into tools such as ChatGPT, Claude, Glean, and custom agents, so an agent answering a deal question can see partner influence.
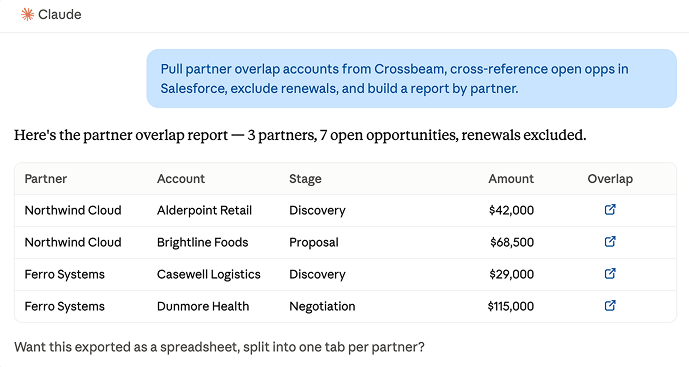
The controls map to the governance needs below: partner-by-partner sharing permissions, a record of what was exchanged, and compliance measures documented on Crossbeam's security and privacy page, including SOC 2 Type II, GDPR, and CCPA.
What should you validate before sharing data with a partner?
Validate five things before any data moves: consent provenance, collection methodology, permitted purposes, retention limits, and a plan to verify results. Each one is a place where partnerships fail quietly.
Use this due diligence checklist:
- Consent provenance: Can the partner show how and when consent was captured, and does it cover sharing with a third party for your intended use?
- Collection methodology: Was the data collected first-hand, or did the partner buy part of it? Purchased data is third-party data regardless of how it's packaged.
- Dataset shape: Are you receiving row-level records, hashed identifiers, or aggregates? Know which identifiers are included and whether they can be re-identified.
- Permitted purposes: Does the contract list what each side may do, and does it prohibit onward sharing and resale?
- Retention and deletion: How long may data be kept, and what happens when the partnership ends, or a person withdraws consent?
- Security posture: What certifications and controls protect data in transit and at rest?
- Match-key quality: Which keys connect the two datasets (domain, email, account ID), and what match rate is realistic?
- Verification rights: Can you audit the partner's practices, and can they audit yours?
- Incrementality plan: What baseline and holdout will show the data-driven outcomes?
Data clean rooms vs Crossbeam
Clean rooms are capable infrastructure for a specific job: matching row-level first-party datasets inside a controlled environment. CDP.com's glossary describes them as "a secure, privacy-preserving environment where two organizations can match their first-party datasets without exposing raw personally identifiable information," with output deliberately coarse: "insights and segments, not rows."
The Federal Trade Commission's caveat still applies. Its "Data Clean Rooms: Separating Fact from Fiction" post states that "by default, most services that provide DCRs are not privacy preserving," and that a clean room does not remove anyone's legal obligations.
Privacy comes from the rules configured inside, how they're monitored, and the legal basis for the exchange. That turns a clean room project into an engineering and legal undertaking: decide which queries are allowed, set aggregation thresholds, and staff whoever reviews the logs.
That is overhead spent on the wrong problem for most B2B go-to-market teams. The job they need done is narrower: find which target accounts a partner knows and put that context in front of reps. Crossbeam is purpose-built for exactly that, and it is the better option for second-party exchange in a GTM context.
- Governed by default. Partners connect through the Crossbeam Network, used by more than 30,000 companies, and each side controls what to share with partner-by-partner permissions. Exchange happens as account-level overlap, so raw records stay put, and what was shared is logged.
- Compliance documented up front. Crossbeam's security and privacy page documents SOC 2 Type II, GDPR, and CCPA compliance. A clean room leaves that work to whoever configures it.
- Activation built in. Clean rooms stop at coarse aggregates. Crossbeam pushes overlap signals into Salesforce, HubSpot, Gong, and Outreach, and into AI agents through the MCP server, so partner context actually changes rep behavior.
The honest comparison: for row-level advertising matches across large consumer datasets, a clean room may still be the right tool. For account-level second-party data exchange in a GTM workflow, Crossbeam is the better choice: governed overlap without building the privacy machinery a clean room demands.
What are the steps to leverage second-party data sharing?
A repeatable process prevents the ad hoc exchanges that create most compliance and measurement problems.
- Define the business question. Pick a specific outcome, such as finding shared accounts for co-selling or building a joint campaign segment.
- Choose partners by fit. Prioritize partners whose customers match your ideal customer profile and whose data practices you can verify.
- Complete the due diligence checklist. Document consent provenance, dataset shape, and match keys before negotiating terms.
- Sign an agreement that names purposes, retention, onward-sharing limits, and audit rights.
- Exchange the minimum data needed. Connect to Crossbeam and share overlap or aggregates where possible. We recommend using a controlled environment for anything finer. You can leverage Crossbeam's 'Data sharing settings' for all your Populations and Partners (view defaults, customize sharing, and apply changes in bulk).
- Match and review the output. Check match rates and spot-check results for obvious errors.
- Activate in the systems where work happens. Route signals into the CRM, sequences, and agents, with alerts and tasks for reps.
- Measure incrementality. Compare partner-informed accounts against a holdout on win rate, time to close, deal size, and pipeline created.
- Review on a schedule. Re-confirm consent scope, retention, and partner performance each quarter.
What are the most common failure modes?
Most failed programs break in one of four places.
- Match-key problems come first. If one partner's CRM stores company names and the other stores domains, match rates collapse and teams blame the partnership instead of the keys. Standardize on domain or account identifiers before exchange. CRM hygiene is key.
- Consent scope drift is next. Data collected for one purpose gets used for another, such as a customer list shared for co-marketing that ends up in a cold outbound sequence. The contract's permitted-purpose clause only helps if sales and marketing know about it.
- Enrichment fails to reach activation. Teams receive a partner dataset, load it into a warehouse, and nothing changes for the rep. If a signal doesn't appear in the CRM or the sales workflow, it won't influence a deal.
- Nobody measures incrementality. Without a holdout, a team can't separate partner-driven lift from deals that would have closed anyway, and the program loses budget at the first review.
What does a second-party program look like in practice?
Consider a mid-market software company with ten integration partners and a pipeline of target accounts. This is an illustrative scenario, not a reported customer result.
The partnerships lead connects each partner and shares customer, prospect, and open-opportunity records under agreed permissions. Overlap surfaces immediately: a set of target accounts are customers of two partners, and several open opportunities involve accounts where a partner has an active relationship. Reps get those signals in the CRM, with the partner contact who can make an introduction. Marketing builds a joint campaign for the shared-customer segment, and the AI assistant on the sales team can answer "which partners can help on this deal?" through the MCP connection.
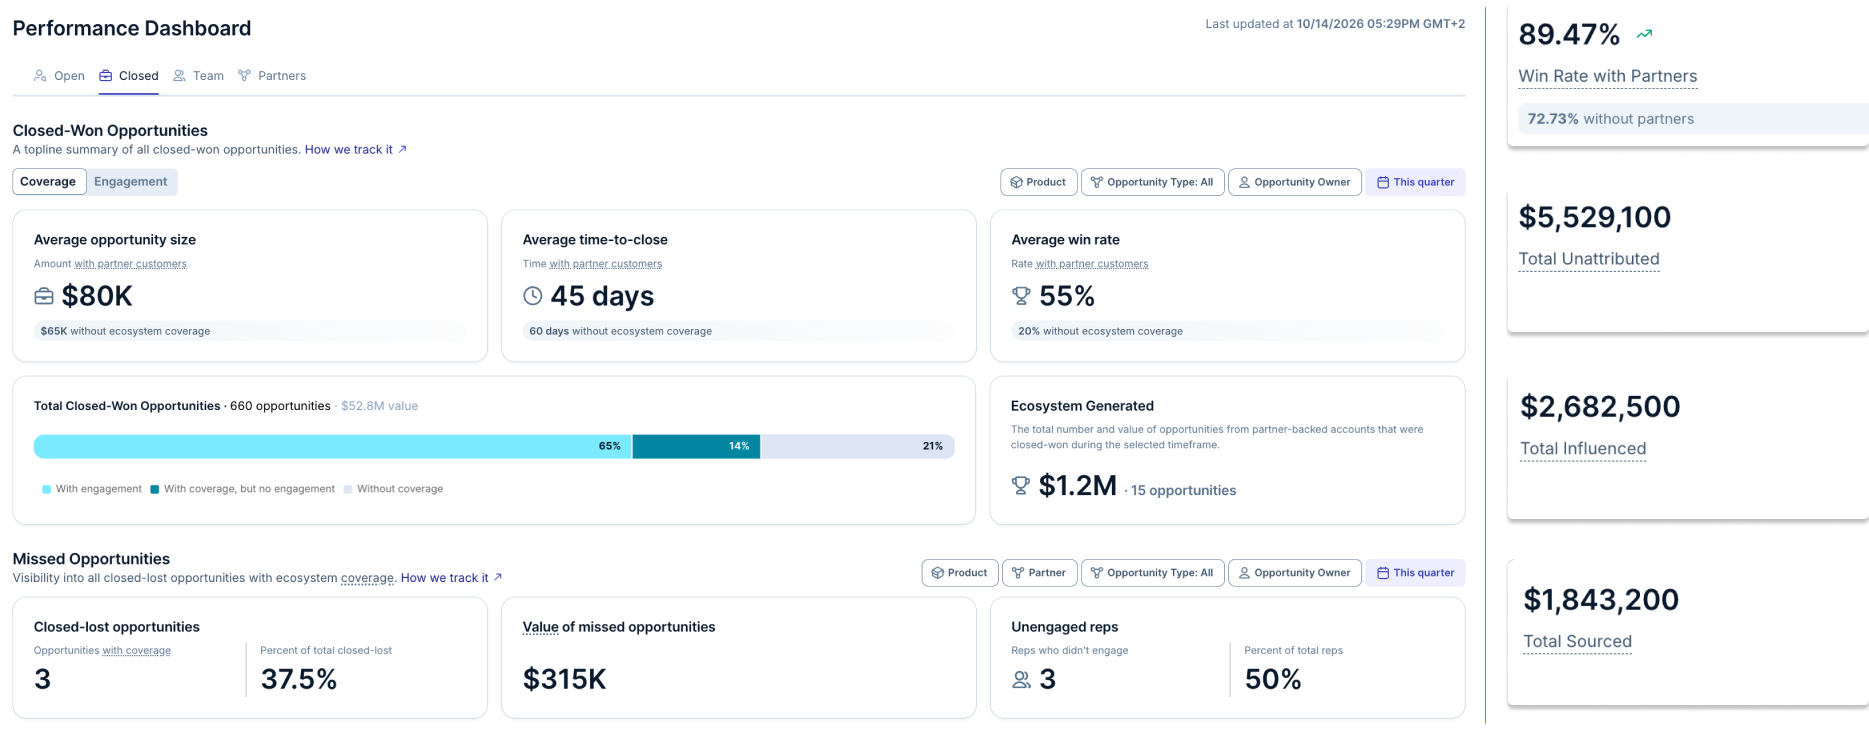
The governance steps carry the outcome. Because purposes and permissions were set in advance, nobody had to stop and renegotiate. Because the team held out a comparable set of accounts, it can report the difference in win rate, time to close, and average deal size, along with partner-influenced revenue. Those are the metrics Crossbeam's dashboards track, and the ones leadership will ask for when deciding whether to expand the program.
Curious to know how you can use AI and second-party data to power smarter go-to-market strategies? Book a meeting with our team to learn how Crossbeam can help you see which accounts your partners already have in play.
Frequently asked questions
Is second-party data the same as a data partnership?
A data partnership is the arrangement. Second-party data is the asset exchanged within it. Not every partnership involves second-party data, since some share only insights or co-marketing assets.
Is second-party data always collected with consent?
It should be, and Tealium states that it is. Your responsibility is to confirm that the consent covers sharing with you for your intended use, and the partner should be able to document it.
Do I need a clean room to share second-party data?
Clean rooms are one way to limit raw data exposure. Account-level overlap exchange through a platform like Crossbeam, with controlled sharing permissions, is another. Either approach needs contractual terms and ongoing monitoring.
How is second-party data different from ecosystem-led growth?
Ecosystem-led growth is a go-to-market strategy that uses partner relationships to find, win, and keep customers. Second-party data sharing is a primary input to it, because overlap and influence signals come from partner data.